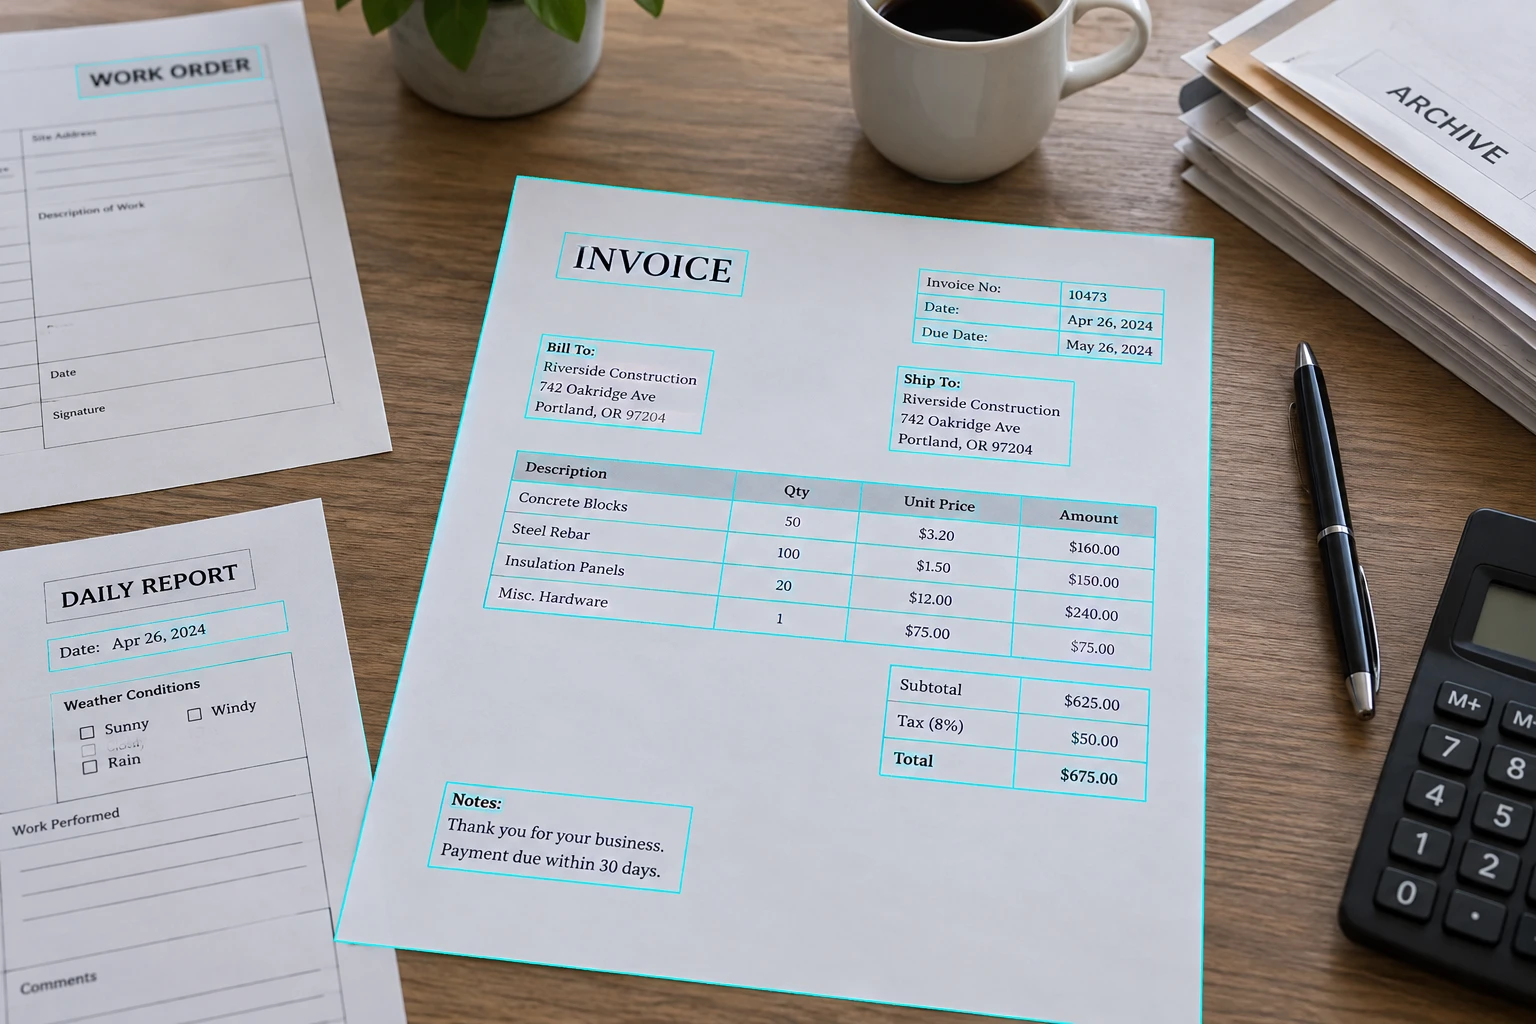
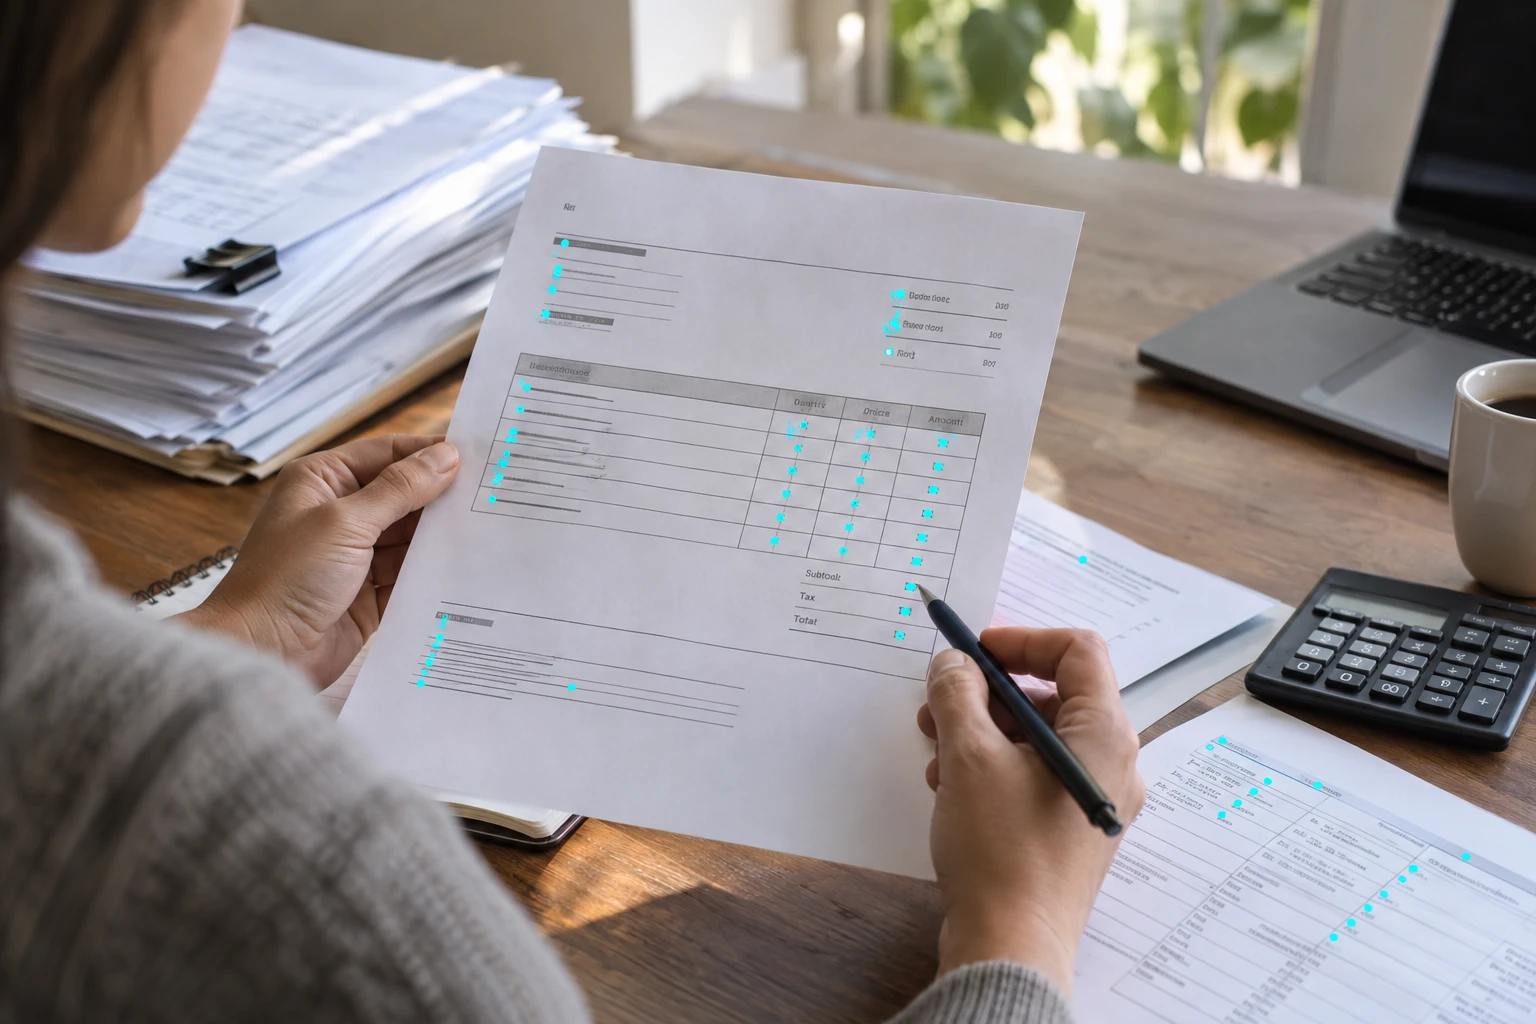
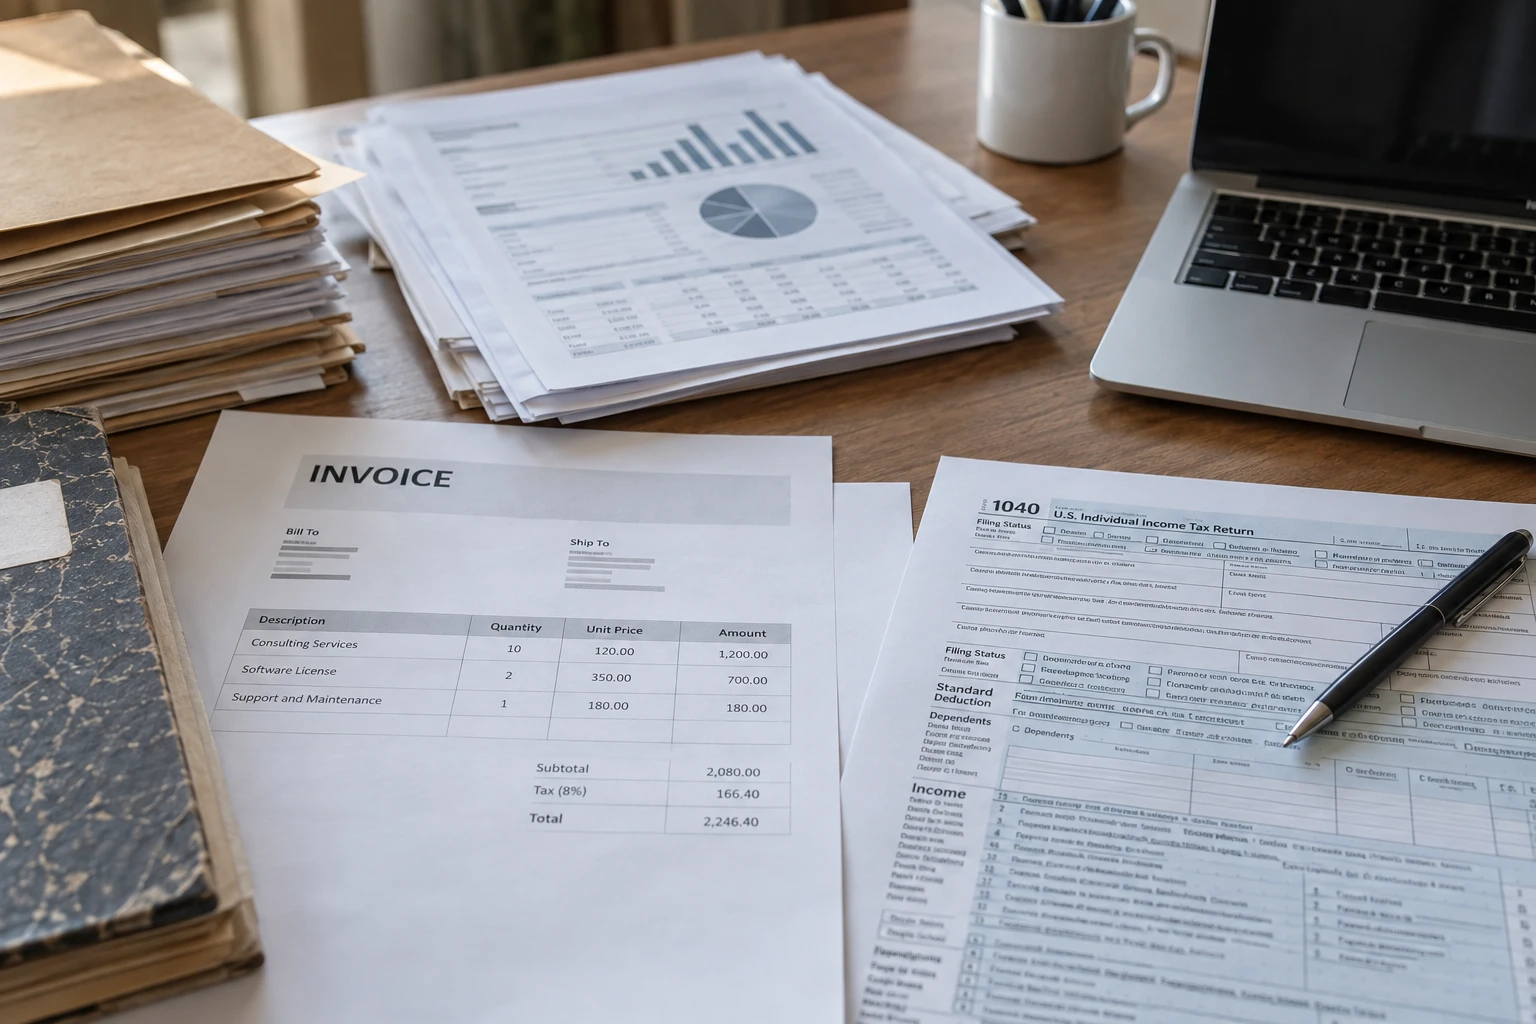
Invoice field extraction
Challenge
Invoice templates place the same information in different locations.
Our approach
Label supplier, date and line-item fields with normalized field names.
Invoices, forms, reports and scanned archives need labels that capture real operational detail. Engai prepares documents datasets around your objects, scenes and review requirements.
Trusted by leading brands

Document Annotation services for a wide range of computer vision applications.
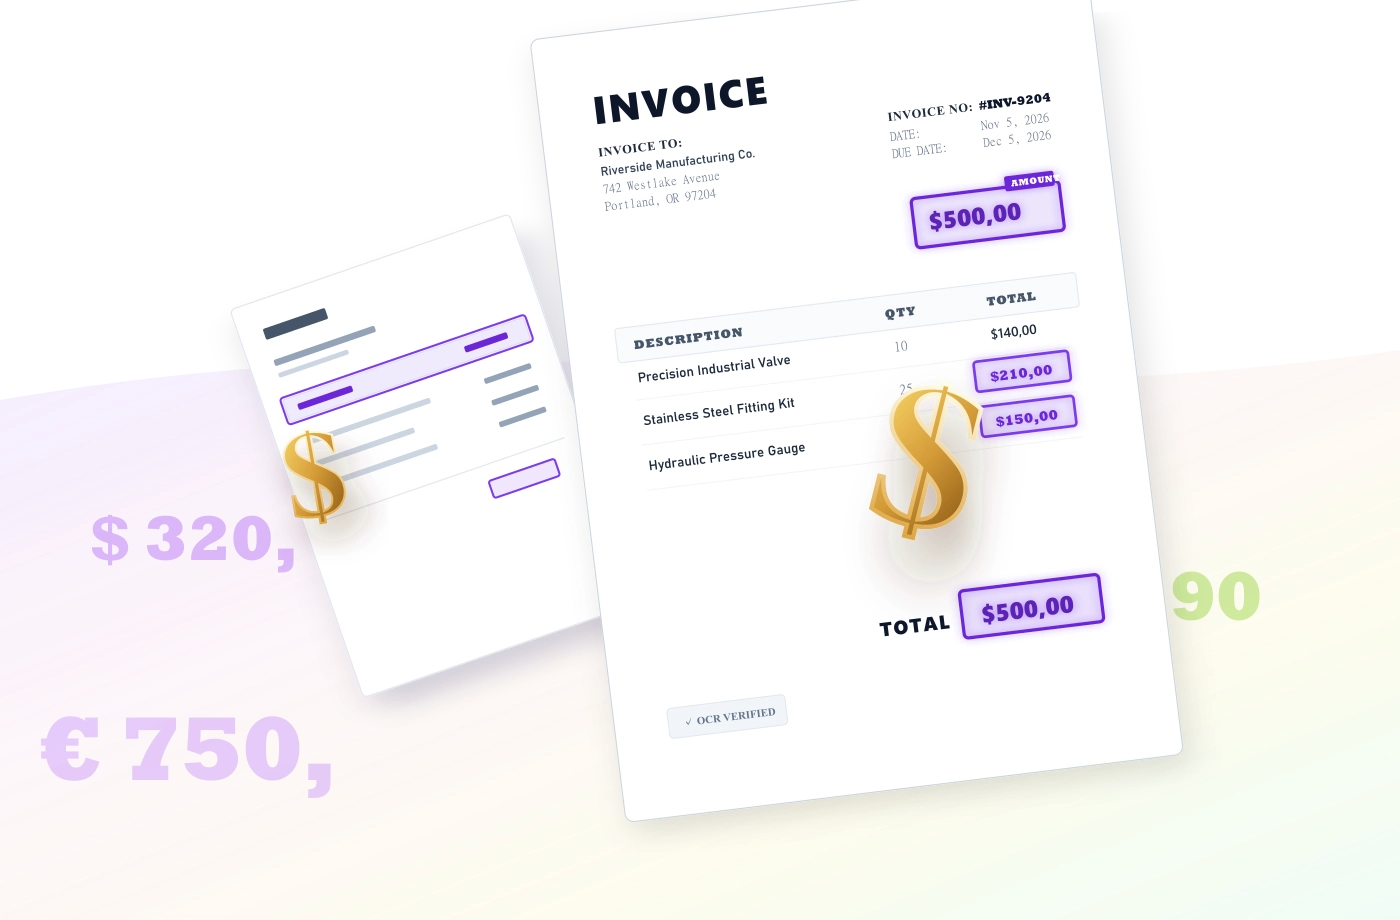
We employ in-house teams to help you annotate a variety of documents, such as invoices, cheques, bills, and even newspapers and magazines. All paper documents are different. If you need to train your computer vision model to read them all, we are here to help.
This doesn't just apply to paper - computer vision can learn to read text in different environments such as billboards, license plates, road signs, and so on. Any company that trains AI for real-world applications can benefit from accurate document annotation.
Carefully annotated data for documents perception, automation and research.
Invoice templates place the same information in different locations.
Label supplier, date and line-item fields with normalized field names.
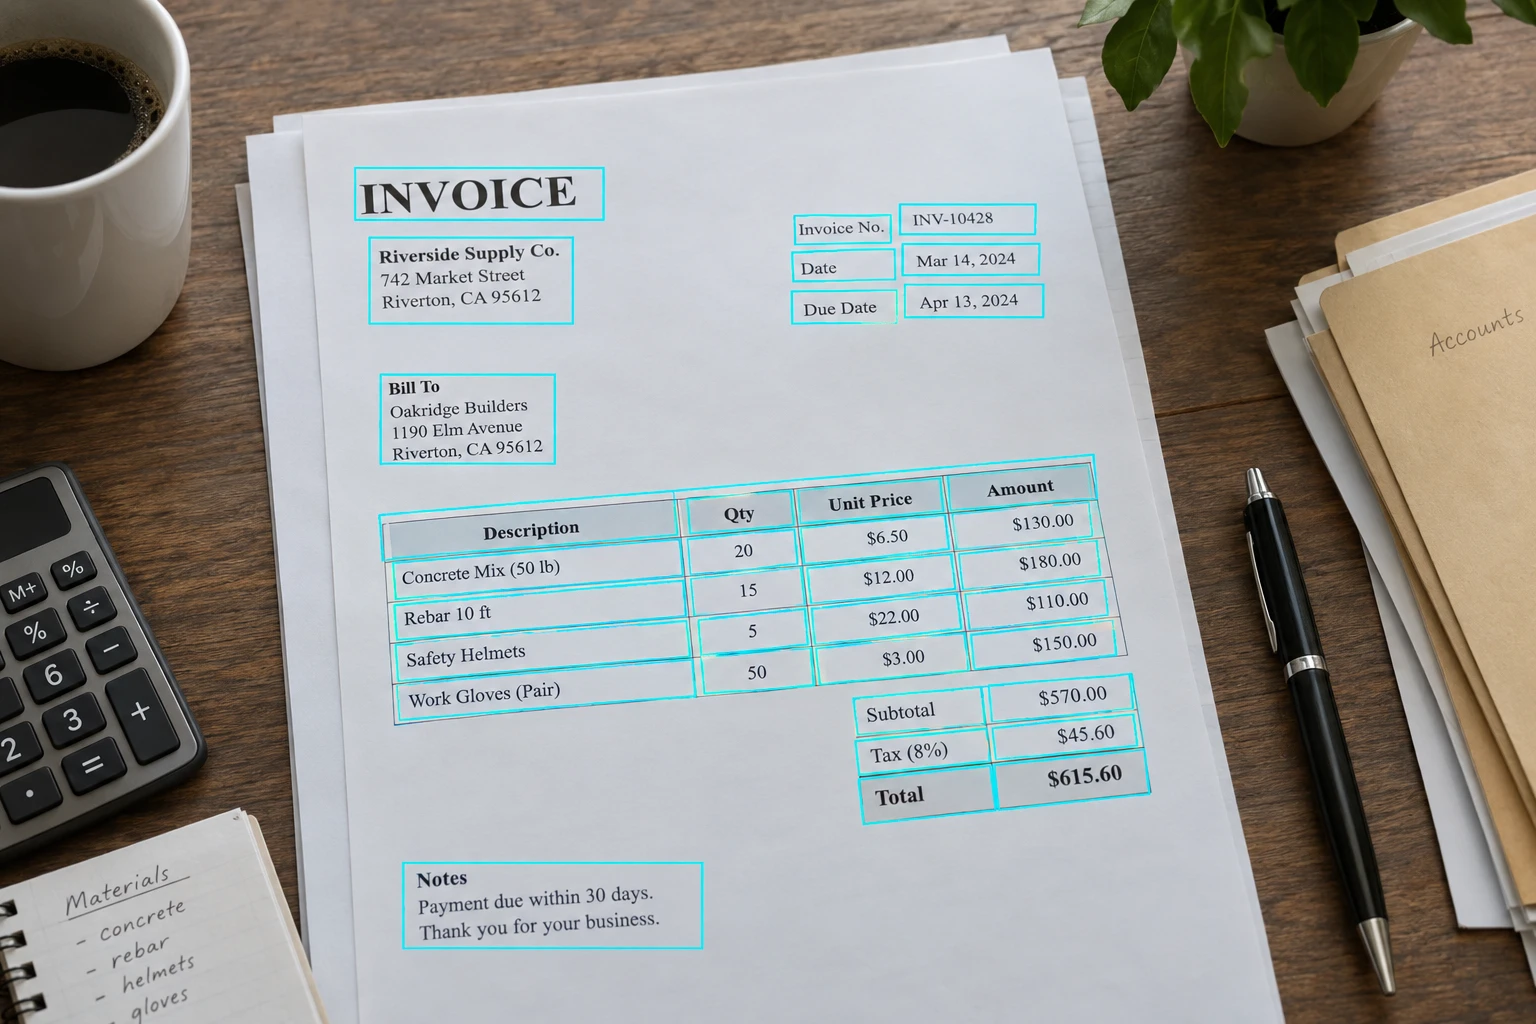
Define classes for text regions, fields and table cells, with visual examples and explicit boundary rules.
Review the effects of lighting, scale and occlusion in invoices, forms, reports and scanned archives.
Connect documents labels to source identifiers, scene metadata and the export schema your model uses.
Annotation capabilities
Invoices, forms, reports and scanned archives need labels that capture real operational detail. Engai prepares documents datasets around your objects, scenes and review requirements.
Locate each visible object with an axis-aligned rectangle and a class label. Applied to text regions, fields and table cells.
Label supplier details, dates and line items while preserving links between extracted text and source regions.
Segment headings, paragraphs, tables and footnotes into a consistent layout hierarchy.
Map form fields and table relationships to stable schemas across varied document templates.
Organize reports, forms and correspondence by agreed categories and representative edge cases.
Annotate reading order and document structure to support retrieval from scanned collections.
The sample batch helped us agree on how to handle overlapping leaves and partially visible crops.
Having those edge cases discussed early would give our team a clearer baseline before scaling annotation.
Our labeling requirements evolved as we reviewed the imagery. The feedback process felt straightforward.
A shared set of examples and regular checkpoints would help keep the dataset consistent across batches.
Field images are rarely perfect. We appreciated the attention to shadows, occlusion and changes in lighting.
These are the details we would want a labeling partner to consider when preparing data for crop-monitoring models.
Annotation applications across documents workflows.
Invoice templates place the same information in different locations.
Label supplier, date and line-item fields with normalized field names.
Reviewed field extraction data with a consistent label schema and documented edge cases.
A project target for improving throughput with task-specific training data.
Where calibrated source imagery supports fine spatial measurements.
A project target for reducing review effort through assisted labeling.
Build your workflow around the infrastructure your team uses.
Secure local processing for sensitive datasets.
Highly scalable infrastructure powered by AWS/GCP.
Real-time inference optimized for on-device hardware.
 ONNX
 TensorRT
 Core ML
 OpenVINO
 LiteRT
 TorchScript
 PaddlePaddle
 IMX500
 Qualcomm
 Huawei
Available formats depend on your model, runtime and target hardware.
fill up this form to send your pilot request
Discover how Engai's Data Pipeline and AI Infrastructure platform can make your organization AI-ready:
Automatically discover and map all datasets with contextualized inventory
Effortlessly manage ML lifecycle and address governance gaps
Drastically reduce deployment time by mitigating edge-case risks
Immediately detect and respond to model drift to minimize threat impact
Proactively apply zero-trust protection mechanisms for proprietary data
Your requirements and proprietary sample assets are encrypted in transit and never used for public model training.